1 - Classical Text Retrieval
Every day, billions of queries hit search engines, email clients, and document archives. The core challenge is always the same: given a short query, find the most relevant items in a large collection. This chapter introduces the classical methods that solve this problem for text.
Text retrieval was one of the earliest problems in computer science to receive serious attention. Beginning in the 1950s, researchers like Gerard Salton and Karen Spärck Jones developed methods that worked remarkably well. The reason is fundamental: queries and documents share the same vocabulary. When a user types “climate change policy”, the system can match those exact words in documents without needing to bridge different representations. This directness gave text retrieval a head start over image or audio search, where the gap between raw data and human meaning is far wider.
By the early 2000s, many considered text retrieval a solved problem. The core algorithms were mature, search engines worked well enough, and research attention shifted elsewhere. Recent developments in generative AI have changed the picture. Modern language models depend on precise, up-to-date text passages retrieved from external sources, and suddenly the quality of the retrieval stage matters more than ever. Classical text retrieval is no longer just the backbone of search engines. It is a critical component in modern AI systems.
We begin with Boolean filtering, the simplest approach, and trace the evolution toward ranked retrieval models that estimate how relevant each document is. Along the way, we develop the feature extraction pipeline that transforms raw text into searchable representations.
Figure 1 traces this six-decade evolution, from Salton’s SMART system through BM25 to its current role as the fast first-stage retriever in retrieval-augmented generation pipelines. The optional reading below describes each milestone.
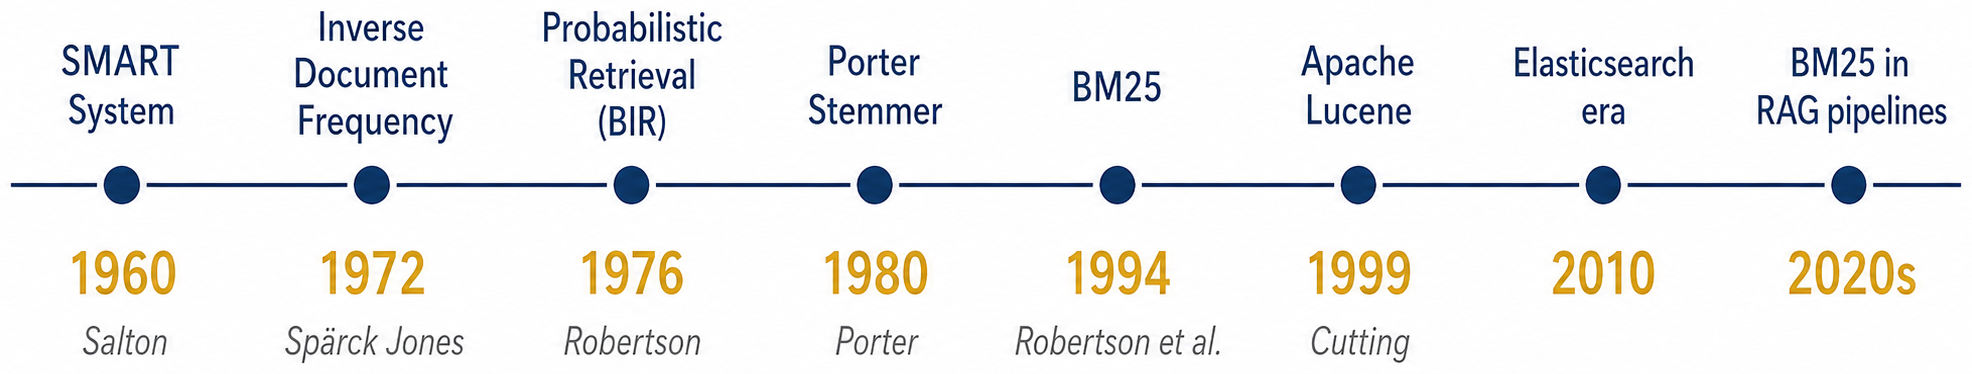
Figure 1:Evolution of classical text retrieval: key milestones, methods, and contributors from the 1960s to the present.
The milestones behind modern text search (optional reading)
1960 - SMART System (Salton): Gerard Salton’s SMART system at Cornell was the first to treat documents and queries as vectors in a term space. It established the experimental methodology that the entire IR field still uses today.
1972 - Inverse Document Frequency (Spärck Jones): Karen Spärck Jones proposed weighting terms by how rarely they appear across documents. This single idea remains the foundation of every term-weighting scheme in use, including BM25.
1976 - Probabilistic Retrieval / BIR (Robertson): Stephen Robertson formalized retrieval as a probability estimation problem: how likely is this document to be relevant? This gave term weighting a theoretical grounding beyond heuristics.
1980 - Porter Stemmer (Porter): Martin Porter published a simple suffix-stripping algorithm that reduced English words to common stems. Despite its errors, it became the de facto standard and is still the default stemmer in many search engines.
1994 - BM25 (Robertson et al.): The Okapi BM25 ranking function combined saturating term frequency, document-length normalization, and probabilistic IDF into a single formula. It outperformed all prior models and remains the default in production search systems.
1999 - Apache Lucene (Cutting): Doug Cutting released Lucene as open-source Java, making high-quality full-text search accessible to any developer. It became the engine underneath Solr, Elasticsearch, and OpenSearch.
2010 - Elasticsearch era: Elasticsearch wrapped Lucene in a distributed, JSON-based API. Suddenly, BM25-powered search scaled to billions of documents with minimal configuration.
2020s - BM25 in RAG pipelines: Large language models need retrieved context to answer questions accurately. BM25 serves as the fast first-stage retriever in Retrieval-Augmented Generation, proving that 30-year-old algorithms still earn their place in modern AI systems.