Ranked Retrieval over Inverted Files
Boolean retrieval returns an unordered candidate set. The ranked models from Classical Text Retrieval, the binary independence model (BIR), the vector space model, and BM25, go further: they assign each document a score so we can return the best matches first. This section shows that all three run over the same inverted index. What changes is the content of the postings and the function that turns them into a score.
Retriever and ranker
Ranked retrieval separates into two stages, shown in Figure 1. The retriever uses the inverted index to gather candidates, taking the union of the postings lists of the query terms, the same merge as a Boolean OR. The ranker then scores each candidate with the model’s scoring function and keeps the top results. An optional filter can drop candidates that fail a metadata condition before ranking; we return to filtering in the next section.
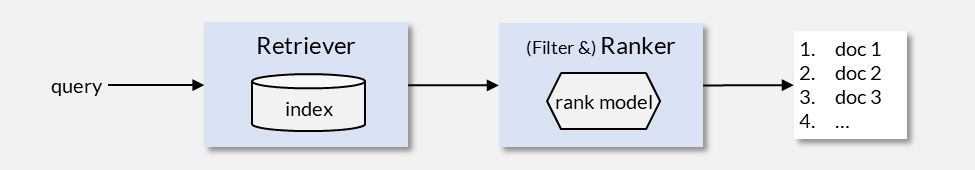
Figure 1:The two-stage pipeline: a retriever gathers candidates from the index, and a filter-and-ranker scores them into a ranked list.
The retriever only needs candidates with at least one query term, because a document with no query term scores zero under all three models. This is the same efficiency argument as before: we score a small candidate set, not the whole collection.
Two evaluation strategies
There are two natural orders in which to walk the postings and accumulate scores. We show both using the BIR model because its scoring function, a sum of per-term weights , is additive and involves no term frequencies or document lengths, so the evaluation logic is fully visible without extra lookups.
Term-at-a-time (TAAT)
The most direct extension of the set-based Boolean evaluation from the previous section processes one query term fully before moving to the next. For each term we walk its postings list and add that term’s weight to a running score for the document. After all terms are processed, the score dictionary holds every candidate’s final score, and we extract the top .
def search_TAAT(query, k):
    query_vector = analyzer.set_of_words(query)
    # filter terms and obtain c_j-weights
    # returns a list of pairs (term_j, c_j)
    term_weights = query_weights(query_vector)

    scores = defaultdict(int)

    # iterate over terms and their postings
    for (term, weight) in term_weights:
        for doc_id in index[term]:
            # add this term's c_j to the document's running score
            scores[doc_id] += weight

    # avoid a full sort: use a heap to extract the top k
    topk = TopKList(k)
    for doc_id, score in scores.items():
        topk.add(doc_id, score)
    return topk
TAAT mirrors what we did with Boolean sets: read one term’s postings, then the next, then combine. The difference is that instead of intersecting or uniting, we accumulate weights. Its simplicity comes at a cost: the scores dictionary can grow very large when a query contains common terms with long postings lists, and we cannot prune early because a document’s score is incomplete until the last term is done.
Document-at-a-time (DAAT)
DAAT instead extends the sorted-stream merge from the end of the previous section. Rather than processing one term fully, it advances all query-term streams in parallel and produces one candidate at a time, in document-ID order. Each candidate receives its complete score the moment it appears, so we can feed it directly into a bounded top- heap.
def search_DAAT(query, k):
    query_vector = analyzer.set_of_words(query)
    # filter terms and obtain c_j-weights
    term_weights = query_weights(query_vector)

    # get iterators for each term and fetch the first posting
    iters = [iter(index[term]) for (term, _) in term_weights]
    nexts = [next(it, None) for it in iters]

    topk = TopKList(k)

    while not all(e is None for e in nexts):
        # the smallest doc ID across all stream heads
        smallest = min(nexts, key=lambda x: x or math.inf)

        # score: sum c_j for every term whose head equals smallest
        score = 0
        for j in range(len(nexts)):
            if nexts[j] == smallest:
                score += term_weights[j][1]
        topk.add(smallest, score)

        # advance every stream whose head was the smallest
        for i, e in enumerate(nexts):
            if e == smallest:
                nexts[i] = next(iters[i], None)

    return topk
DAAT reads postings as streams and never builds a full score dictionary. Memory is bounded by the heap size . Because the full score is known the moment a document is emitted, DAAT can also prune: once the heap is full, it can skip candidates whose maximum possible score cannot enter the top (techniques such as WAND exploit this). The price is slightly more complex bookkeeping in the inner loop.
Comparison
Both strategies read the same postings and consider the same candidates, so their asymptotic cost is similar. TAAT is the clearer extension of the Boolean set approach and a fine choice for short queries. DAAT is generally preferred in production because of its bounded memory and its ability to prune.
The three models over postings
The models differ only in what the postings store and how a candidate is scored.
For BIR, the postings need only document identifiers. Each query term carries a weight derived from relevance feedback, and a document’s score is the sum of the over the query terms it contains. No term frequencies or document lengths are involved.
For the vector space model, the DAAT and TAAT patterns remain the same, but instead of summing a single per query term, we sum the product for each query term present in the document. Expanding the TF-IDF weights, each term’s contribution is . As a consequence, the postings for term must store not only the document identifier but also the term frequency so the ranker can compute that product.
Using the inner product alone (the sum above) already gives a useful ranking that favors documents sharing many weighted terms with the query. The cosine measure refines this by normalizing both vectors:
The query norm is not a problem: we have the full query vector and can compute it once per query. The document norm is the difficulty. During evaluation, whether DAAT or TAAT, we see only the subset of document components that overlap with the query terms, not the full document vector, so we cannot compute the norm from what we read. The solution is to store each document’s length (or precomputed norm) in a separate table, indexed by document identifier. This adds one random lookup per candidate document.
BM25 faces the same requirement: its length-normalization factor uses the document length and the average document length , which likewise must be stored alongside the index. The cost is modest, a single integer or float per document, but it is a structural addition beyond the postings themselves.
For BM25, the postings again store term frequencies, and the ranker additionally needs the document length (the total number of term occurrences in , not the vector norm ), the average document length , and the parameters and .
A worked BM25 example
We index the titles of the 50-book library collection from Performance Evaluation, applying the standard pipeline of tokenization, stop-word removal, and stemming. This gives documents with an average title length of tokens. We run the query “database systems”, which the pipeline reduces to the stems “databas” and “system”, with and .